PartImageNet
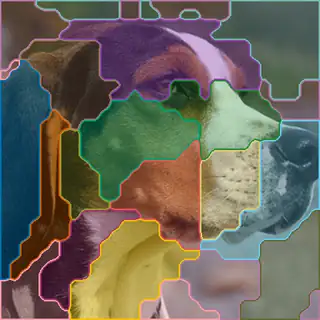
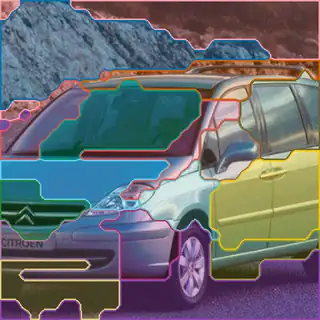
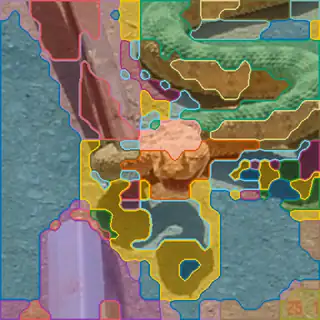
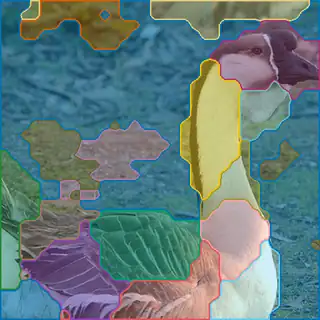
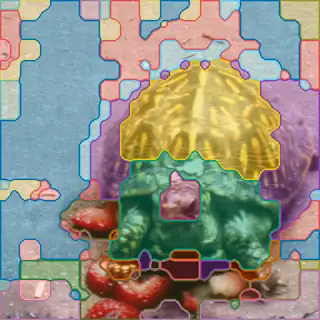
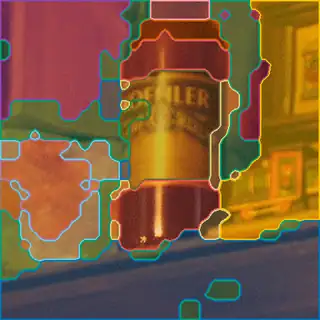
A frozen DINOv2 ViT-B/14 backbone with a dictionary of 1,024 concepts, up to 16 per image, and 16 quantized attributes of 64 values each. Across its 20,466 training images, a typical image has 16.
 DisParQ
/
A frozen DINOv2 ViT-B/14 backbone with a dictionary of 1,024 concepts, up to 16 per image, and 16 quantized attributes of 64 values each. Across its 20,466 training images, a typical image has 16.